
nvidia/ai-factory-operations-agent
Developer toolsこのページは AI により自動翻訳されています。技術的な詳細は原文をご確認ください。 原文を見る
AIエージェントをデプロイし、クラスターの問題点を調査し、管理されたAI工場の業務を合理化します.
概要
専門性の高いAIエージェントをデプロイし、クラスターの問題を調査し、管理されたAI工場の業務を合理化します。 実験的なリリースです。 インストール前の「サポート」をご覧ください。 AIファクトリー・オペレーション・エージェントは、NemoClawで構築された拡張可能なエージェント・オペレーション・フレームワークを展開するためのNVIDIAの青写真です。 専門エージェントは、クラスターシステム全体でエビデンスを集め、相関するエビデンスを集め、明確な根本原因の要約を生成し、各チームが独自のAI工場環境に適応できる、監査可能なワークフローを通じて、次の手順を推奨します。 - 読まれたKubernetesのworkloadおよびクラスターの点検。 - Prometheus と VictoriaMetrics のクエリと Grafana ダッシュボードの作成。 - スケジュール者およびログ証拠からのSlurmの仕事の根本原因の分析。 - 任意クラスター管理統合。 - 監査可能なエージェントワークフローでサンドボックスされたコマンド実行。 OpenShell は一般的なエージェントのコマンド実行を隔離します.
概要(AI 翻訳)
専門性の高いAIエージェントをデプロイし、クラスターの問題を調査し、管理されたAI工場の業務を合理化します。
概要
[!NOTE] 実験的なリリースです。 インストール前の「サポート」をご覧ください。
AIファクトリー・オペレーション・エージェントは、NemoClawで構築された拡張可能なエージェント・オペレーション・フレームワークを展開するためのNVIDIAの青写真です。 専門エージェントは、クラスターシステム全体でエビデンスを集め、相関するエビデンスを集め、明確な根本原因の要約を生成し、各チームが独自のAI工場環境に適応できる、監査可能なワークフローを通じて、次の手順を推奨します。
サポートされているワークフローは次のとおりです。
- 読まれたKubernetesのworkloadおよびクラスターの点検。
- Prometheus と VictoriaMetrics のクエリと Grafana ダッシュボードの作成。
- スケジュール者およびログ証拠からのSlurmの仕事の根本原因の分析。
- 任意クラスター管理統合。
- 監査可能なエージェントワークフローでサンドボックスされたコマンド実行。
アーキテクチャ
OpenShell は一般的なエージェントのコマンド実行を隔離します。 Kubernetes、observability、Slurm、およびベースコマンドマネージャアクセスは、モジュール固有のサーバーサイドツールと、これらのモジュールのために明示的に設定された資格情報を使用します.
このページは AI により自動翻訳されています。技術的な詳細は原文をご確認ください。
README
以下は原文 README の抜粋です。原文を見る。
AI Factory Operations Agent
Deploy specialized AI agents to investigate cluster issues and streamline governed AI factory operations.
Overview
[!NOTE] This is an experimental release. Please reference SUPPORT.md prior to installation.
AI Factory Operations Agent is an NVIDIA blueprint for deploying an extensible agentic operations framework built with NemoClaw. Specialized agents gather and correlate evidence across cluster systems, generate clear root cause summaries, and recommend next steps through governed, auditable workflows that teams can adapt to their own AI factory environments.
Supported workflows include:
- Read-only Kubernetes workload and cluster inspection.
- Prometheus and VictoriaMetrics queries and Grafana dashboard creation.
- Slurm job root-cause analysis from scheduler and log evidence.
- Optional cluster-management integrations.
- Sandboxed command execution with an auditable agent workflow.
Architecture
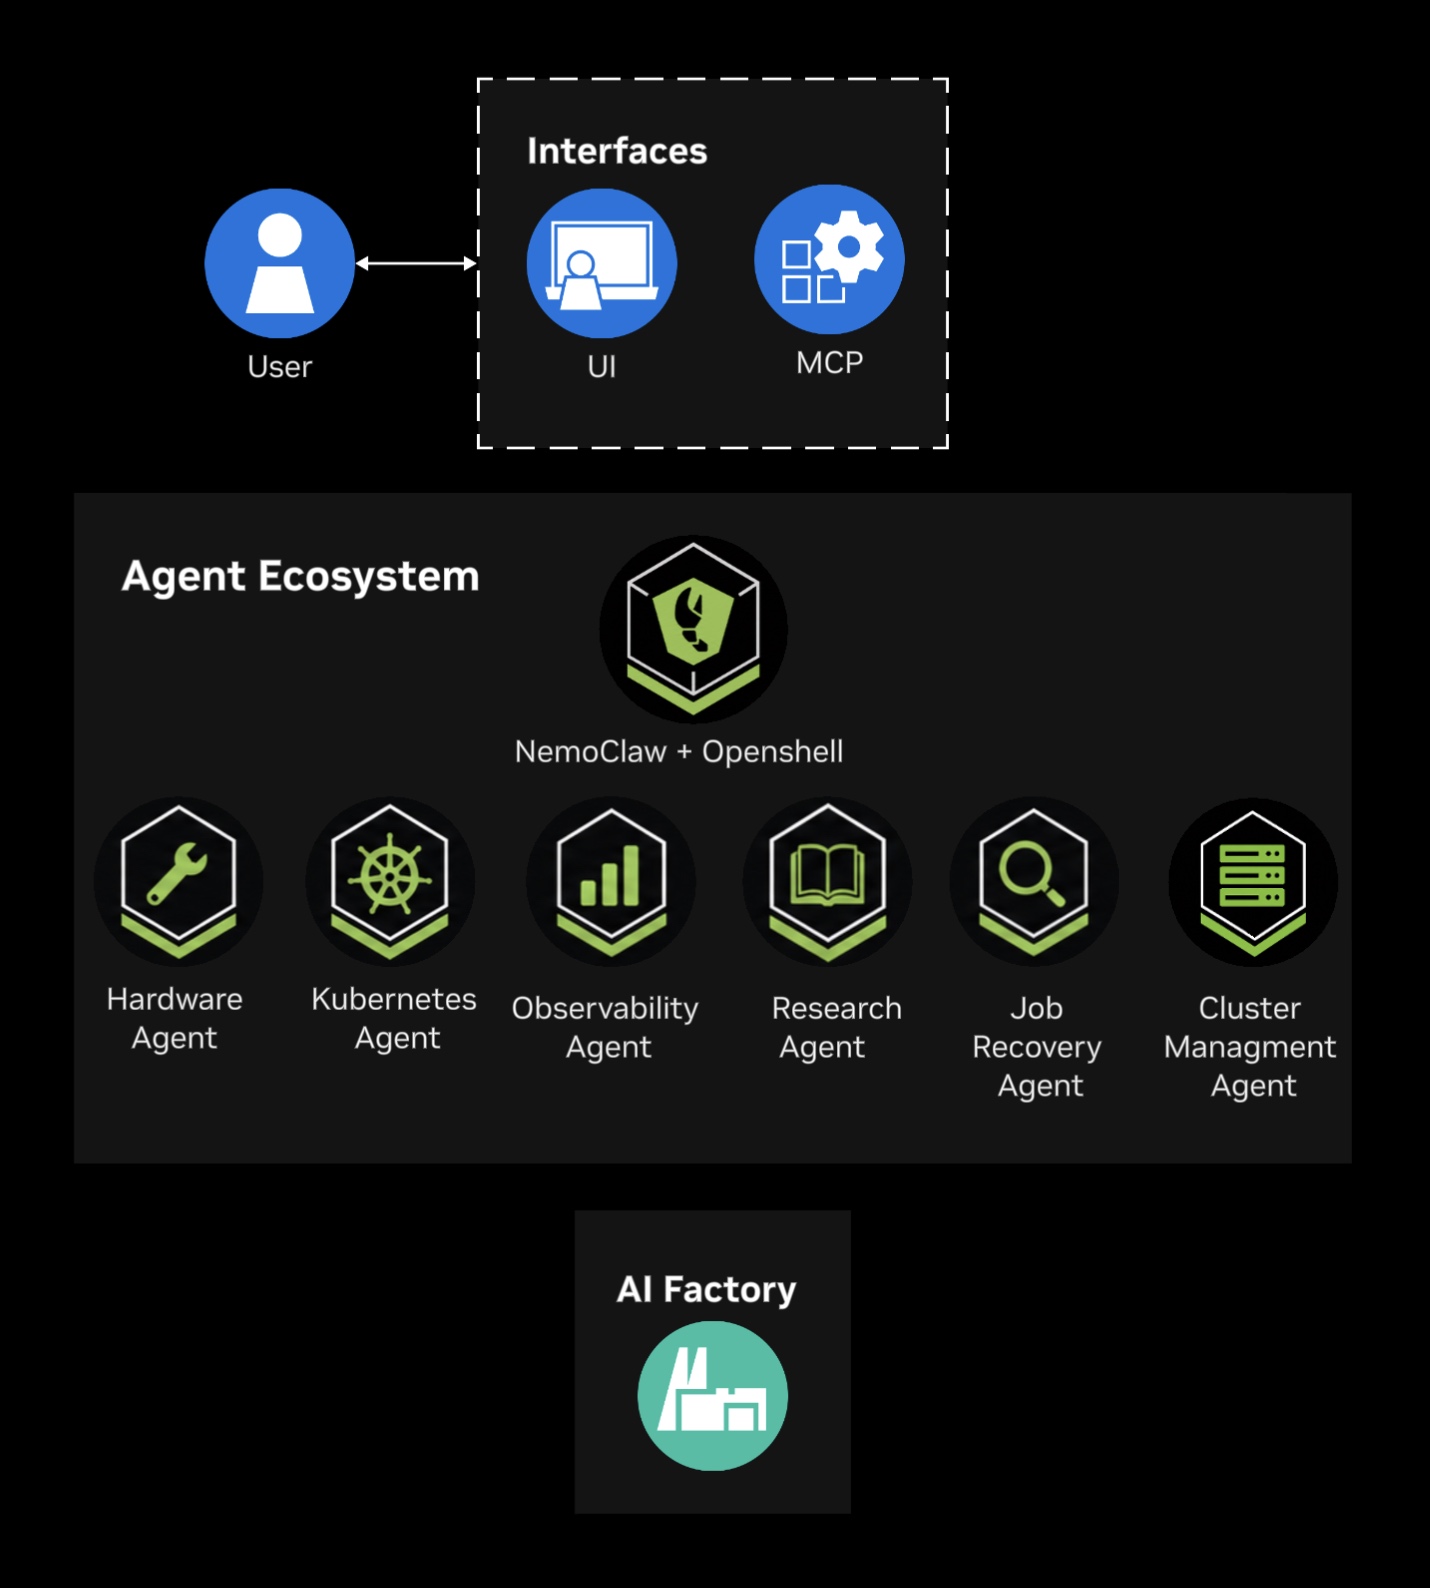
OpenShell isolates general agent command execution. Kubernetes, observability, Slurm, and Base Command Manager access use module-specific server-side tools and the credentials explicitly configured for those modules. Browser and MCP clients do not receive cluster credentials. Kubernetes Secrets remain mounted only in the pods that require them.
Requirements
- OS/architecture: a Kubernetes environment compatible with the container images selected in Helm values.
- Runtime: Kubernetes,
kubectl, and Helm 3. - LLM: an OpenAI-compatible endpoint or a cluster capable of running chart-managed vLLM.
- GPU/driver: required only when deploying chart-managed vLLM; requirements depend on the selected model profile.
- Optional services: Prometheus or VictoriaMetrics, Grafana, Slurm, or cluster-management endpoints for the corresponding modules.
Getting Started
The documentation site can be built locally from the guides in this repository. See Building the documentation.
In the early access stage, the published Helm chart and container images require an early access invitation to the private NGC registry; nvcr.io login alone does not grant pull access. To request access before installing, complete the onboarding form or email [email protected]. You can also contact your NVIDIA account team.
Use the complete installation guide for your environment:
推奨ツール
別のキーワードを試すか、フィルタを外してください。
インストール
npx skillfish add nvidia/ai-factory-operations-agent