
将混乱的文件伪造成带有来源和信任层级的OKF知识包
概览
okfsmith 是一个 Python CLI,能够导入 PDF、markdown、wiki dump,并导出 Notion 规范一致的 OKF v0.2 捆绑包:带有 YAML 前置的 markdown 文件,以及保留的 index.md 和 log.md。每个概念都包含来源(sources[])、信任层和生命周期元数据,每个捆绑包都由内置的 §11 验证器检查。只需一个 MCP 命令即可将其提供给你的代理。 将任何支持MCP的代理指向该捆绑: 展示的工具:八种读取工具(索引、列表、搜索、获取、邻居、遍历、来源、微分)以及四个受监管的写回工具(preview_write_concept、write_concept、update_concept、audit_log)——每个答案都追溯到捆绑包中的来源[],每次写入都未验证、验证者门禁、来源印章和审计记录。 ⭐ 如果okfsmith帮了你,星星意义重大——它能帮助其他开发者找到项目。 Clean Markdown 已经有不错的OKF工具。
概述(AI 翻译)
将混乱的文档锻造成OKF v0.2知识包。
okfsmith 是一个 Python CLI,可以导入 PDF、markdown、wiki dump 和 Notion
导出并发布符合规范的 OKF v0.2 捆绑包:带 YAML 的 markdown 文件
前言,加上保留的index.md和log.md。每个概念都包含
来源(sources[])、信任层、生命周期元数据,以及所有
bundle 由内置的 §11 验证器检查。将其送达给你的代理
一个MCP命令。
60秒快速启动
将任何支持MCP的代理指向该捆绑:
暴露工具:八个读面工具(index、list、search、get,
neighbors、traverse、provenance、diff)加上四个受控写回
工具(preview_write_concept、write_concept、update_concept,
audit_log)——每个答案都追溯到该丛中的sources[],且
每次写入都未验证、验证者门禁、来源戳章,且
已审计记录。
⭐ 如果okfsmith帮了你,星星意义重大——它能帮助其他开发者找到项目。
为什么是 Okfsmith
Clean Markdown 已经有不错的 OKF 工具。中间的混乱——200页的 PDF 阅读顺序紊乱、Notion导出、维基导出——
本页由 AI 翻译,技术细节请以原文为准。
README
以下为原文 README 节选,完整内容请查看原文。
okfsmith


Forge messy documents into OKF v0.2 knowledge bundles.
okfsmith is a Python CLI that ingests PDFs, markdown, wiki dumps, and Notion
exports and emits spec-conformant OKF v0.2 bundles: markdown files with YAML
frontmatter, plus reserved index.md and log.md. Every concept carries
provenance (sources[]), a trust tier, and lifecycle metadata, and every
bundle is checked by a built-in §11 validator. Serve it to your agents with
one MCP command.
60-second quickstart
pip install okfsmith

okfsmith init ./kb
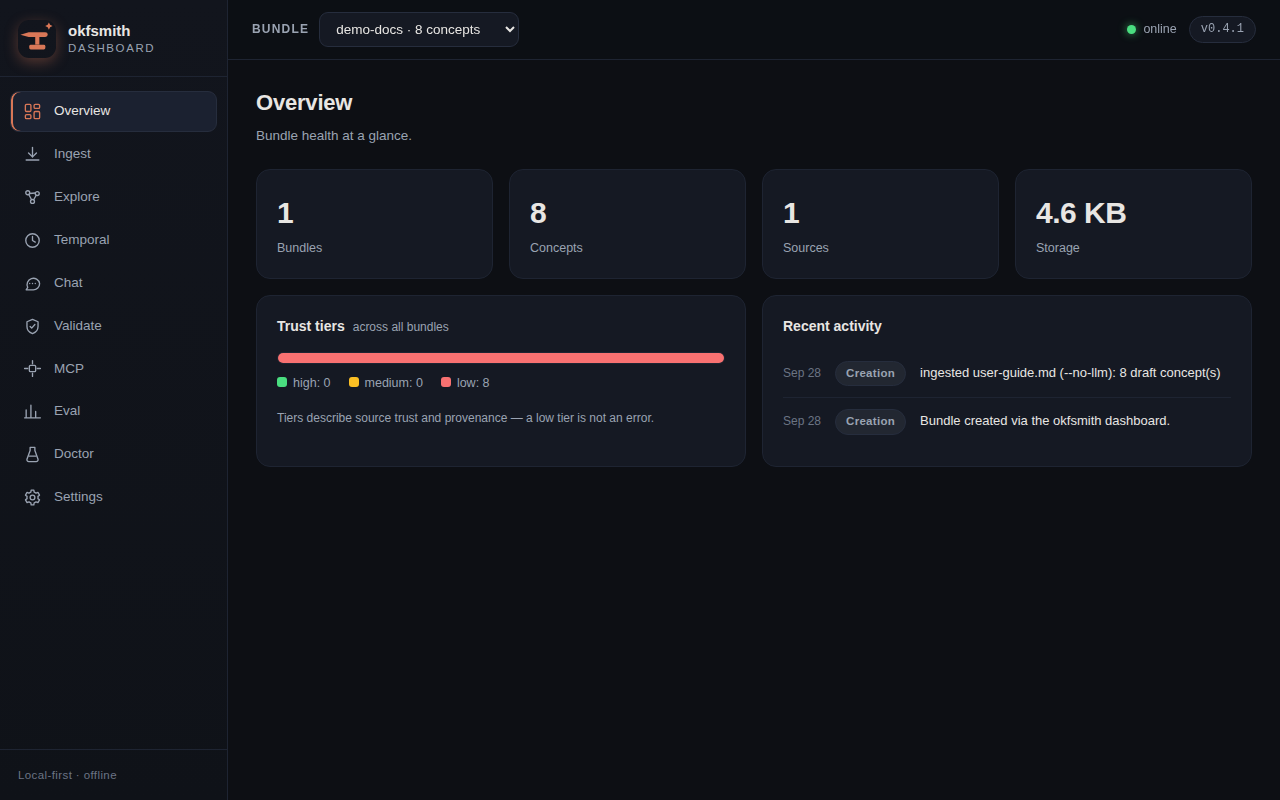
okfsmith ingest ./kb notes/ report.pdf --no-llm   # offline first pass
okfsmith validate ./kb
okfsmith graph ./kb --format html   # writes ./kb/viz.html — open in a browser
Point any MCP-capable agent at the bundle:
pip install "okfsmith[mcp]"
okfsmith mcp ./kb
Tools exposed: eight read tools (index, list, search, get,
neighbors, traverse, provenance, diff) plus four governed write-back
tools (preview_write_concept, write_concept, update_concept,
audit_log) — every answer traces back to sources[] in the bundle, and
every write lands unverified, validator-gated, provenance-stamped, and
audit-logged.
⭐ If okfsmith helped you, a star means a lot — it helps other developers find the project.
Why okfsmith
Clean markdown already has good OKF tooling. The messy middle — 200-page PDFs with broken reading order, sprawling Notion exports, wiki dumps — is where knowledge usually lives, and that’s what okfsmith ingests first:
parse → section → extract → link → emit → validate → serve
- Tiered parsing, free first. Tier 1 is local and keyless: LiteParse for
PDFs, stdlib parsing for markdown/text. Office formats (
.docx,.pptx,.xlsx) via the optionalokfsmith[office]extra; Docling OCR sidecar viaokfsmith[ocr]for scanned pages. PyMuPDF is deliberately avoided (AGPL). - Two extraction modes.
--no-llmwrites one draft concept per section — fast, offline, deterministic. With an LLM (Ollama by default, or an
推荐工具
换一个关键词,或者移除筛选条件。
安装
npx skillfish add bilal-junaid-jiwani/okfsmith