
ShinkaEvolve : Towards Open-Ended and Sample-Efficient Program Evolution 🧬
Обзор
ShinkaEvolve : Towards Open-Ended and Sample-Efficient Program Evolution 🧬
README
ShinkaEvolve: Towards Open-Ended and Sample-Efficient Program Evolution 🧬
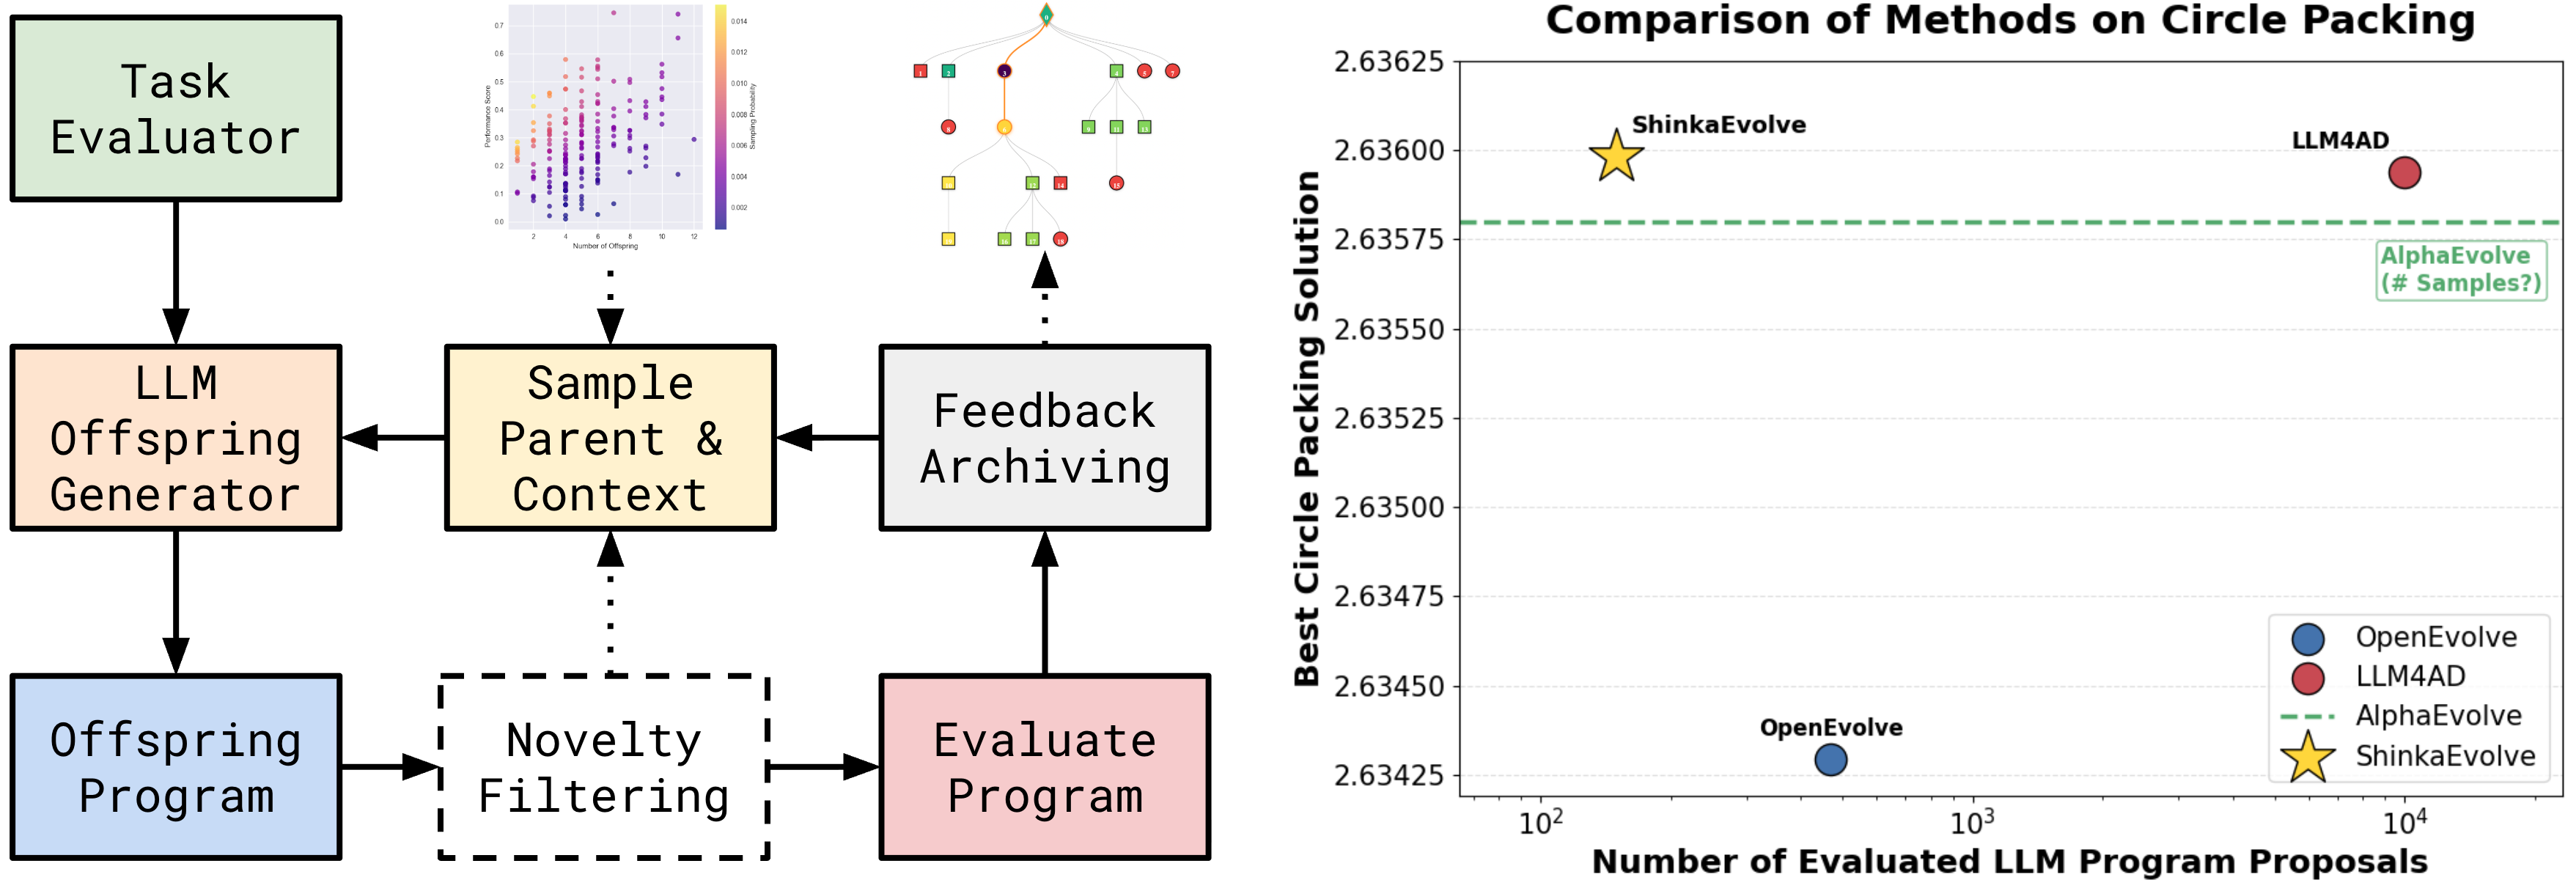
shinka is a framework that combines Large Language Models (LLMs) with evolutionary algorithms to drive scientific discovery. By leveraging the creative capabilities of LLMs and the optimization power of evolutionary search, shinka enables automated exploration and improvement of scientific code. The system is inspired by the AI Scientist, AlphaEvolve and the Darwin Goedel Machine: It maintains a population of programs that evolve over generations, with an ensemble of LLMs acting as intelligent mutation operators that suggest code improvements.
May 2026 Update: Added Headless CLI-backed mutation models for subscription-backed agent usage. Use model strings such as headless/[email protected]?effort=high or headless/claude. Check the example for more detail.
Apr 2026 Update: Added the new documentation website with guides for getting started, configuration, async evolution, local models, WebUI usage, and agentic workflows.
Mar 2026 Update: Refactored API and unified runner ShinkaEvolveRunner (replacing EvolutionRunner and AsyncEvolutionRunner). You can now install shinka via PyPI and uv: pip install shinka-evolve.
Feb 2026 Update: Added agent skills for using shinka within coding agents (Claude Code, Codex, etc.) for new task generation (shinka-setup), converting your repo (shinka-convert), evolution (shinka-run), and result inspection (shinka-inspect). Install them via npx:
npx skills add SakanaAI/ShinkaEvolve --skill '*' -a claude-code -a codex -y
Jan 2026 Update: ShinkaEvolve was accepted at ICLR 2026 and we released an update with new features.
Nov 2025 Update: Rob gave several public talks about our ShinkaEvolve effort (Official, AutoML Seminar).
Oct 2025 Update ShinkaEvolve supported Team Unagi in winning the ICFP 2025 Programming Contest.
The framework supports parallel evaluation of candidates locally or on a Slurm cluster. It maintains an archive of successful solutions, enabling knowledge transfer between different evolutionary islands. shinka is particularly well-suited for scientific tasks where there is a verifier available and the goal is to optimize performance metrics while maintaining code correctness and readability.
Documentation 📝
| Guide | Description | What You’ll Learn |
|---|---|---|
| 🚀 First steps | Installation, basic usage, and examples | Setup, first evolution run, core concepts |
| 📓 Tutorial | Interactive walkthrough of Shinka | Hands-on examples, config, best practices |
| ⚙️ Config | Comprehensive config reference | All config options & advanced features |
| 🎨 WebUI | Interactive visualization and monitoring | Real-time tracking, result analysis, debugging |
| ⚡ Async Evo | High-perf. throughput (5-10x speedup) | Concurrent processing, proposal/eval tuning |
| 🧠 Local Models | How to use local LLMs and embeddings with Shinka | Running open-source models & integration tips |
| 🤖 Agentic Use | Run Shinka with Claude/Codex skills | CLI install, skill placement, setup/run workflows |
Installation & Quick Start 🚀
# Install from PyPI
pip install shinka-evolve

# Or with uv
uv pip install shinka-evolve

# Run your first evolution experiment
shinka_launch variant=circle_packing_example
The distribution name is shinka-evolve; Python imports stay import shinka.
shinka_launch still supports the original shorthand group overrides:
shinka_launch variant=circle_packing_example
shinka_launch task=novelty_generator database=island_small
Built-in Hydra presets ship inside the package under shinka/configs/. To add your own presets from a PyPI install without cloning the repo, place them in your own config directory and pass --config-dir:
mkdir -p ~/my-shinka-configs/variant
$EDITOR ~/my-shinka-configs/variant/my_variant.yaml
shinka_launch --config-dir ~/my-shinka-configs variant=my_variant
For development installs from source:
git clone https://github.com/SakanaAI/ShinkaEvolve
cd ShinkaEvolve
uv venv --python 3.11
source .venv/bin/activate  # On Windows: .venv\Scripts\activate
uv pip install -e .
For detailed installation instructions and usage examples, see the Getting Started Guide.
Examples 📖
| Example | Description | Environment Setup |
|---|---|---|
| ⭕ Circle Packing | Optimize circle packing to maximize radii. | LocalJobConfig |
| 🎮 Game 2048 | Optimize a policy for the Game of 2048. | LocalJobConfig |
| ∑ Julia Prime Counting | Optimize a Julia solver for prime-count queries. | LocalJobConfig |
| 🔥 Fortran Heat Diffusion | Optimize a compiled Fortran stencil solver. | LocalJobConfig |
| 🧮 Wolfram GCD Sum | Optimize a Wolfram Language GCD-sum solver. | LocalJobConfig |
| ✨ Novelty Generator | Generate creative, surprising outputs (e.g., ASCII art). | LocalJobConfig |
| ∿ Sine Approx Headless | Evolve a bounded sine approximation using Headless subscription-backed mutation calls. | LocalJobConfig |
| ⚡ RTLLM PPA | Evolve Verilog RTL for power/performance/area under a fixed spec (RTLLM v2.0). Requires iverilog + yosys + OpenSTA. |
LocalJobConfig |
shinka Run with Python API 🐍
For the simplest setup with default settings, you only need to specify the evaluation program:
from shinka.core import ShinkaEvolveRunner, EvolutionConfig
from shinka.database import DatabaseConfig
from shinka.launch import LocalJobConfig, SlurmCondaJobConfig, SlurmDockerJobConfig

# Minimal - only specify what's required
job_conf = LocalJobConfig(eval_program_path="evaluate.py")
# Or source a uv/venv environment per job:
# job_conf = LocalJobConfig(
#     eval_program_path="evaluate.py",
#     activate_script=".venv/bin/activate",
# )
# Or run evaluations on SLURM:
# job_conf = SlurmCondaJobConfig(
#     eval_program_path="evaluate.py",
#     partition="gpu",
#     time="01:00:00",
#     cpus=1,
#     gpus=1,
#     mem="8G",
#     conda_env="shinka",
# )
# Or run evaluations in a Docker container on SLURM:
# job_conf = SlurmDockerJobConfig(
#     eval_program_path="evaluate.py",
#     image="ubuntu:latest",
#     partition="gpu",
#     time="01:00:00",
#     cpus=1,
#     gpus=1,
#     mem="8G",
# )
db_conf = DatabaseConfig()
evo_conf = EvolutionConfig(init_program_path="initial.py")

runner = ShinkaEvolveRunner(
    evo_config=evo_conf,
    job_config=job_conf,
    db_config=db_conf,
    max_evaluation_jobs=2,
    max_proposal_jobs=3,  # modest oversubscription when proposal generation is slower than eval
    max_db_workers=4,
)
runner.run()
Live model pricing
Shinka refreshes supported model metadata and token prices from
models.dev when a new run starts. Requests use HTTP
cache validation, then fall back to the last validated user-cache response or
the packaged snapshot when offline. The exact catalog used by a run is written
to pricing_snapshot.json in its results directory and reused when that run is
resumed.
Set SHINKA_PRICING_MODE=offline to skip the network check, or
SHINKA_PRICING_MODE=required to fail startup when live pricing cannot be
validated. Run shinka_models --verbose to inspect catalog provenance and the
models available for configured provider credentials.
Weights & Biases logging
Install the optional W&B integration and enable it for a run:
pip install 'shinka-evolve[wandb]'

# Authenticate online runs. In CI, provide this through a secret manager.
export WANDB_API_KEY=

shinka_run --task-dir examples/circle_packing \
  --results_dir results/circle_wandb \
  --num_generations 20 \
  --set evo.enable_wandb_logging=true \
  --set evo.wandb_project=shinka-evolve
W&B logging is additive: the existing SQLite database and WebUI logging remain
enabled. Each evaluated individual logs score/individual against generation,
along with compact evaluation, cost, and timing metrics. Resuming the same
results directory reuses its persisted W&B run ID by default. Online mode uses
the credentials from wandb login or WANDB_API_KEY; use wandb_mode=offline
to record locally without uploading. See
Configuration
for all W&B options.
Evaluation Setup & Initial Solution 🏃
To use ShinkaEvolveRunner, you need two key files: The evaluate.py script defines how to test and score your programs - it runs multiple evaluations, validates results, and aggregates them into metrics that guide the shinka evolution loop. The initial.py file contains your starting solution with the core algorithm that will be iteratively improved by LLMs across generations.
shinka Launcher with Hydra 🚀
shinka Launcher utilizes Hydra to configure and launch evolutionary experiments effortlessly. It supports concise configuration via Hydra’s powerful override syntax, making it easy to manage and iterate scientific explorations.
# Run with the shared default baseline
shinka_launch

# Run with custom parameters
shinka_launch \
    task=circle_packing \
    database=island_large \
    evolution=small_budget \
    cluster=local \
    evo_config.num_generations=20
For comprehensive configuration options and advanced usage, see the Configuration Guide.
shinka_run Agent CLI 🤖
shinka_run is a task-directory launcher for async evolution. It is designed for agent workflows and does not require Hydra config files.
# Inspect full interface (detailed help)
shinka_run --help

# Minimal run
shinka_run \
    --task-dir examples/circle_packing \
    --results_dir results/circle_agent_run \
    --num_generations 20

# Run with keyword overrides
shinka_run \
    --task-dir examples/circle_packing \
    --results_dir results/circle_agent_custom \
    --num_generations 50 \
    --max-evaluation-jobs 6 \
    --set db.num_islands=2 \
    --set job.time=00:10:00 \
    --set job.activate_script=.venv/bin/activate \
    --set evo.llm_models='["gpt-5-mini","gemini-3-flash-preview"]'

# Load optional YAML config (relative to --task-dir), then override via --set
shinka_run \
    --task-dir examples/circle_packing \
    --config-fname shinka_small.yaml \
    --results_dir results/circle_agent_from_yaml \
    --num_generations 50 \
    --set db.num_islands=2
--task-dir must contain evaluate.py and initial..
--config-fname can define evo/db/job (or evo_config/db_config/job_config) plus max_evaluation_jobs/max_proposal_jobs/max_db_workers and verbose/debug.
Precedence: config YAML < --set < authoritative flags.
--results_dir and --num_generations are authoritative and always override config/--set values for evo.results_dir and evo.num_generations.
Headless Agent Models
Use headless/ model strings to route mutation calls through the local Headless CLI instead of provider API clients. Shinka uses npx -y @roberttlange/headless by default and runs headless --check before evolution starts.
shinka_run \
    --task-dir examples/sine_approx_headless \
    --results_dir results/sine_approx_headless \
    --num_generations 5 \
    --max-evaluation-jobs 1 \
    --max-proposal-jobs 1 \
    --set evo.llm_models='["headless/[email protected]?effort=high"]' \
    --set evo.embedding_model=null \
    --set evo.patch_types='["full", "diff"]' \
    --set evo.patch_type_probs='[0.5, 0.5]'
For a Python runner using both Codex and Claude through Headless:
python examples/sine_approx_headless/run_evo.py
Interactive WebUI 🎨
Monitor your evolution experiments in real-time with Shinka’s interactive web interface! The WebUI provides live visualization of the evolutionary process, genealogy trees, and performance metrics.
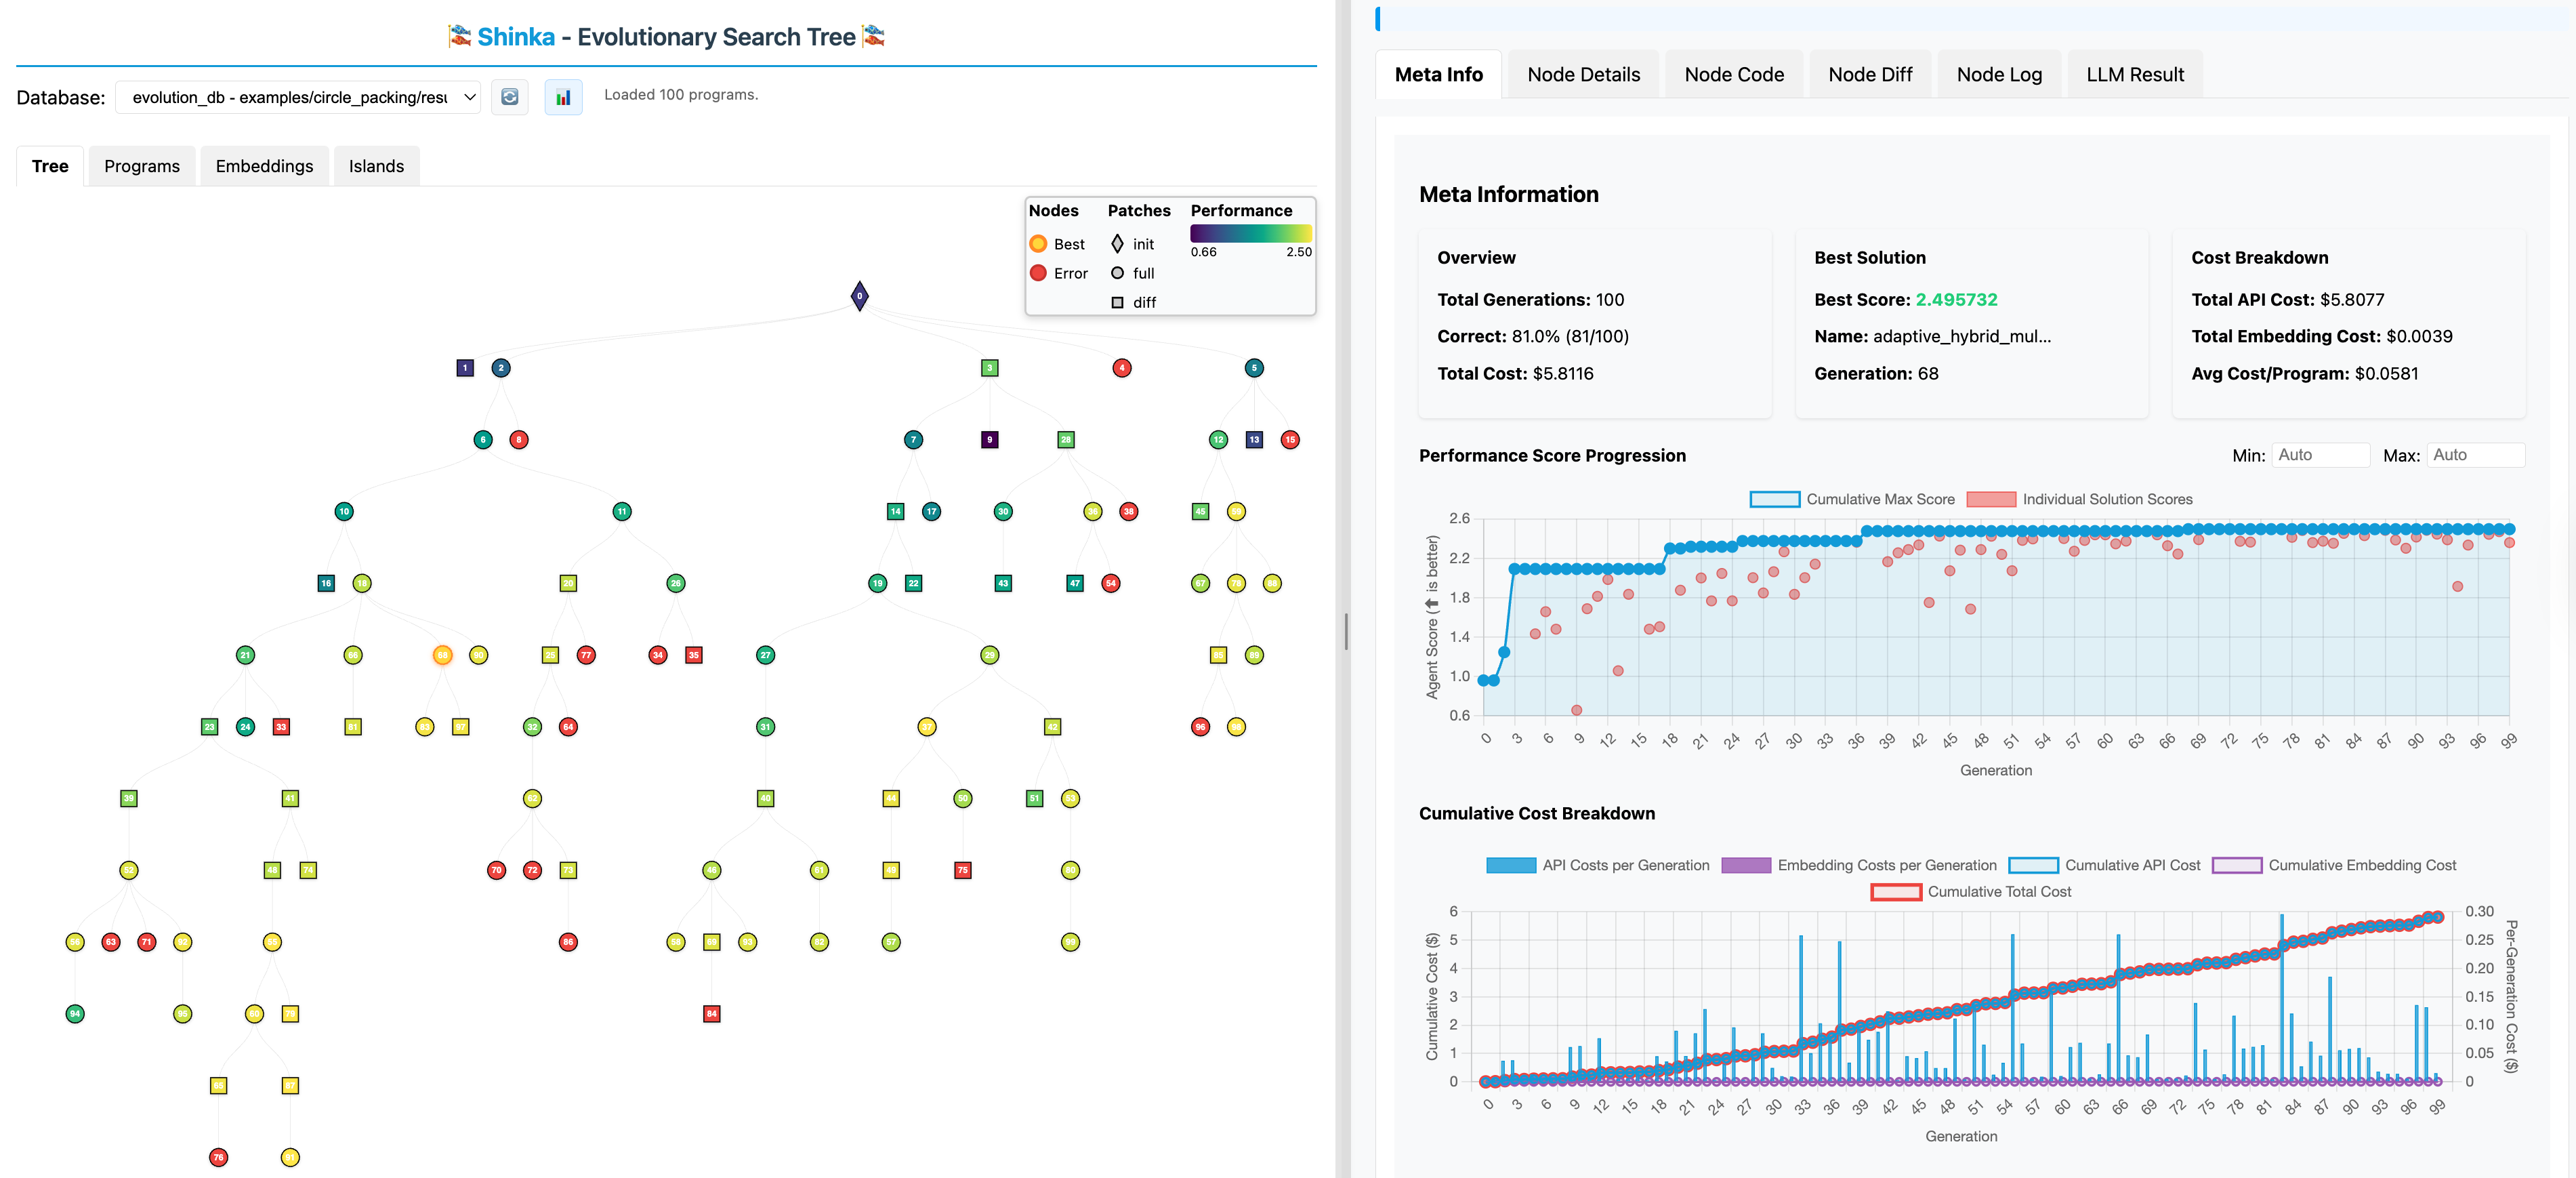
Launch the WebUI alongside your evolution experiment:
# Start your evolution experiment
shinka_launch

# In another terminal, launch the WebUI
shinka_visualize --port 8888 --open
For detailed WebUI documentation, see the WebUI Guide.
Local Docs Development
To preview the documentation site locally on localhost:
uv sync --group docs
uv run --group docs mkdocs serve --dev-addr 127.0.0.1:8000
Then open http://127.0.0.1:8000/.
Contributing 👥
Contributions are welcome across code, docs, representative benchmarks, and bug reports.
Please read the contribution guide before opening an issue or pull request. It documents the expected issue and PR structure, local checks, and the extra evidence required for changes to the core program evolution pipeline.
If you propose a change to the core evolution pipeline, please include results on a representative runnable task that highlights the new capability and compare them against a baseline. Please do not add random benchmark tasks just to justify a PR.
Related Open-Source Projects 🧑🔧
- OpenEvolve: An open-source implementation of AlphaEvolve
- LLM4AD: A Platform for Algorithm Design with Large Language Model
Citation ✍️
If you use ShinkaEvolve in your research, please cite it as follows:
@article{lange2025shinka,
  title={ShinkaEvolve: Towards Open-Ended And Sample-Efficient Program Evolution},
  author={Lange, Robert Tjarko and Imajuku, Yuki and Cetin, Edoardo},
  journal={arXiv preprint arXiv:2509.19349},
  year={2025}
}
Рекомендуемые инструменты
Попробуйте другой запрос или уберите фильтр.
Установка
npx skillfish add sakanaai/shinkaevolve